
Enterprise NVMe SSD Share Jumps in AI Data Center Procurement Lists
Across the global AI infrastructure landscape, one detail keeps showing up in procurement documents, request‑for‑proposal (RFP) packages, and server bill‑of‑materials: the proportion of enterprise NVMe SSDs is rising sharply. As organizations scale out AI training and inference clusters, they are revisiting every layer of the stack to remove bottlenecks, and storage is no exception. Where traditional SATA SSDs and even high‑end HDDs once dominated, enterprise‑grade NVMe SSDs are now claiming a steadily larger share of the storage line items in AI data center procurement lists.
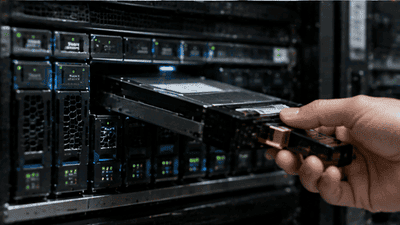
This blog post explores why that share is jumping, what it reveals about evolving AI data center architectures, and how it reshapes economics, design decisions, and vendor strategies. We will look at performance and architectural drivers, procurement behavior, implications for other storage technologies, and practical considerations for buyers and suppliers navigating this shift.
NVMe and the AI data center performance imperative
NVMe (Non‑Volatile Memory Express) is a protocol designed from the ground up to exploit the parallelism and low latency of flash storage. Unlike legacy interfaces such as SATA or SAS, NVMe uses PCIe lanes and a streamlined command set to achieve far higher throughput and lower latency. In an AI data center context—where GPUs and accelerators process enormous datasets—this performance gap is far from academic; it directly affects training times, inference throughput, and overall cluster efficiency.
AI workloads typically involve repeated passes over large datasets, complex model checkpoints, and fast retrieval of intermediate results. If storage cannot keep up, accelerators sit idle waiting for data. Enterprise NVMe SSDs, with their high IOPS, bandwidth, and low latency, align well with these demands, making them an increasingly natural choice in procurement lists for AI‑heavy environments.
From HDD and SATA SSD to NVMe: a mix shift in procurement
Historically, data centers employed a mix of HDDs for bulk capacity and SATA or SAS SSDs for performance‑sensitive workloads. Early AI deployments often reused these existing storage tiers, relying heavily on in‑memory caching to mask some of the limitations. As AI projects scaled, however, the limitations of HDD and SATA SSD became more obvious—particularly in multi‑tenant environments where many jobs compete for I/O.
Procurement teams began to re‑evaluate storage options, focusing on end‑to‑end pipeline performance rather than just raw capacity cost. In many cases, the analysis showed that enterprise NVMe SSDs, while more expensive per gigabyte than HDDs, yielded better utilization of expensive GPUs and accelerators. The net effect on total cost of ownership favored NVMe: saving training time and increasing cluster throughput more than justified the higher storage bill. As these findings filtered through internal reviews and pilot deployments, NVMe storage gained priority in procurement lists, driving a mix shift away from HDD and SATA SSD toward enterprise NVMe SSDs.
Enterprise NVMe vs consumer NVMe in AI environments
It is important to distinguish between enterprise NVMe SSDs and consumer‑grade NVMe drives. Consumer NVMe SSDs, commonly found in laptops and desktops, deliver impressive performance but are optimized for price and typical client workloads. Enterprise NVMe SSDs, by contrast, are designed for sustained high load, rigorous write endurance, advanced error correction, and predictable latency under multi‑tenant access patterns.
AI data centers rely on these enterprise characteristics. Training jobs can generate intensive write patterns during checkpointing, and inference clusters may handle constant high‑volume read operations. Consumer drives can suffer from performance degradation, endurance issues, or inconsistent latency under such stress. Procurement lists that target mission‑critical AI workloads therefore increasingly specify enterprise NVMe SSDs with detailed endurance, performance, and reliability requirements rather than generic NVMe parts.
Architectural trends favoring enterprise NVMe
Several architectural trends in AI data centers reinforce the rising share of enterprise NVMe SSDs. One is the move toward disaggregated and composable infrastructure, where compute, storage, and networking resources are pooled and allocated dynamically. In these architectures, high‑performance storage is essential to avoid creating bottlenecks that undermine the benefits of resource pooling. Enterprise NVMe SSDs, often deployed in NVMe‑over‑Fabrics or high‑bandwidth storage nodes, fit neatly into this model.
Another trend is the increasing use of local NVMe storage near GPUs or accelerators. Many servers now host NVMe drives directly attached via PCIe slots to provide fast local scratch space, caching, and intermediate data storage. This reduces reliance on networked storage for the hottest data and improves locality. As more AI servers adopt such designs, procurement lists naturally include more enterprise NVMe SSDs as standard components of each node.
A third trend is the use of tiered storage within AI clusters, with enterprise NVMe serving as the performance tier above slower flash or HDD tiers. Data most frequently accessed by training jobs or latency‑sensitive inference workloads resides on NVMe SSDs, while colder data sits on other media. This tiered approach increases the total number of NVMe drives in the environment because multiple tiers coexist rather than NVMe replacing other storage outright.
Procurement behavior: from pilot to default choice
The jump in enterprise NVMe SSD share also reflects a change in procurement behavior over time. In the early stages of AI deployment, many organizations treated NVMe as an experimental or pilot technology, limited to certain high‑priority projects. Procurement specifications were narrowly tailored, and NVMe line items were small relative to HDD and SATA SSD entries.
As pilot projects showed strong performance and productivity gains, NVMe moved from experimental to recommended practice, and eventually to default choice for new AI‑capable infrastructure. Procurement teams updated templates, minimum specifications, and reference designs, often codifying NVMe requirements for storage tiers that support AI workloads. Once included as a standard, enterprise NVMe SSDs appear automatically in RFPs and vendor quotes for a broad range of deployments, expanding their share without requiring individual justification for each project.
At the same time, procurement teams became more sophisticated in differentiating enterprise NVMe SKUs. They began to specify endurance classes, performance tiers, interface generations, and feature sets—such as power‑loss protection and namespace support—to match specific AI workload needs. This targeted specification encourages vendors to offer higher‑quality enterprise NVMe SSDs rather than generic offerings, further embedding these products in procurement lists.
Impact on HDD and SATA SSD roles
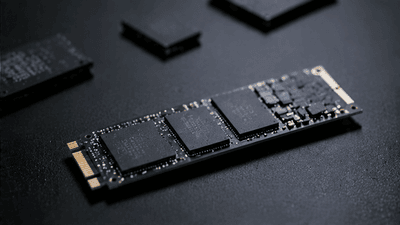
The rise of enterprise NVMe SSDs in AI data center procurement lists inevitably affects the roles of HDDs and SATA SSDs. HDDs, with their mechanical nature and relatively high latency, remain relevant for cold storage and archival data, where cost per gigabyte is paramount and performance less critical. However, their presence in performance‑sensitive AI configurations diminishes as NVMe takes over the hot and warm tiers.
SATA and SAS SSDs, which previously served as performance upgrades over HDDs, now face competition from NVMe on both performance and system design fronts. In AI environments where bandwidth and latency are critical, NVMe’s advantages overshadow the incremental benefit of SATA SSDs over HDDs. As a result, SATA SSDs may be relegated to niche uses or transitional roles, while NVMe becomes the standard for new AI‑oriented deployments.
This shift does not necessarily eliminate HDDs or SATA SSDs from data centers, but it redefines their roles. HDDs carry large volumes of rarely accessed data, SATA SSDs may serve legacy systems or less demanding workloads, and enterprise NVMe SSDs take center stage wherever AI performance matters.
Economic and total‑cost‑of‑ownership considerations
From a pure component perspective, enterprise NVMe SSDs cost more per gigabyte than HDDs and often more than SATA SSDs. However, AI data center procurement teams increasingly evaluate storage through a total‑cost‑of‑ownership (TCO) lens, incorporating performance, energy efficiency, failure rates, and impact on accelerator utilization. Under these broader metrics, enterprise NVMe SSDs often look more attractive.
For example, if faster storage reduces training times by a significant margin, fewer GPUs may be needed to achieve the same results, or existing GPUs can handle more workloads over a given period. This can offset the higher storage cost. Similarly, the energy efficiency and reliability of enterprise NVMe SSDs can reduce power, cooling, and maintenance expenses compared with HDDs or lower‑quality drives. When these factors are quantified, the net benefit of NVMe becomes clear, supporting its prominence in procurement decisions.
As organizations gain experience with these TCO calculations, they tend to institutionalize the results, adjusting their procurement policies to prioritize NVMe for AI workloads. Over time, this pushes enterprise NVMe SSD share higher because decisions become standardized rather than evaluated individually for each project.
Vendor strategy shifts: NVMe‑centric portfolios
Storage and server vendors have responded to the rising importance of enterprise NVMe SSDs by reshaping their portfolios. Many now offer NVMe‑optimized server designs, dedicated NVMe storage arrays, and reference architectures specifically tailored for AI and high‑performance computing. These offerings bundle enterprise NVMe SSDs with appropriate controllers, networking, and software stacks, simplifying procurement and deployment for customers.
Vendors also increasingly position their enterprise NVMe SSDs as strategic products rather than mere components. They emphasize endurance, data protection features, telemetry, and integration with management tools. Some provide specialized firmware or caching algorithms optimised for AI workloads, further differentiating their drives. These strategies help vendors capture value in a segment where performance and reliability are essential, and they encourage customers to specify branded enterprise NVMe SSD solutions directly in procurement lists.
The competitive landscape among SSD vendors is also shifting. Companies that excel in enterprise NVMe design and integration gain an advantage in AI data center RFPs, where technical specifications and proven deployments carry significant weight. Those primarily focused on client or commodity SSDs may find it harder to win AI contracts, prompting them to invest more in enterprise‑class NVMe offerings or partner with others to remain relevant.
Operational implications for AI data centers
The rising share of enterprise NVMe SSDs in procurement lists has operational consequences. Data center teams must adapt their monitoring, maintenance, and lifecycle management practices to NVMe characteristics. This includes tracking drive health metrics, managing firmware updates, and optimizing placement and tiering policies for data across NVMe and other media.
NVMe’s higher performance capabilities also influence how workloads are scheduled and balanced. Storage administrators may need to refine throughput and latency expectations, adjusting application configurations and resource allocation schemes to avoid underutilizing NVMe capacity or overburdening particular nodes. In multi‑tenant AI environments, careful planning ensures that NVMe benefits are distributed fairly among workloads, preventing “noisy neighbor” effects.
As NVMe becomes more central, organizations must also plan for replacement cycles and capacity upgrades. Given the intense usage patterns of AI workloads, enterprise NVMe SSDs may reach their endurance limits faster than drives in traditional environments. Proactive replacement and capacity planning help avoid unexpected failures and maintain consistent performance as the cluster evolves.
Practical considerations for buyers revising procurement lists
For buyers updating their AI data center procurement lists, several practical steps can help align storage decisions with current trends. First, it is important to clearly categorize workloads by performance and reliability requirements. Workloads that are central to AI training, interactive inference, or time‑critical analytics should be mapped to enterprise NVMe SSD tiers, while archival and lower‑priority workloads can remain on HDD or slower flash tiers.
Second, procurement documents should include detailed specifications for enterprise NVMe SSDs—covering endurance, performance classes, interface generations, form factors, and key features like power‑loss protection and data security. Generic NVMe specifications may not be sufficient; they risk vendors proposing drives that do not meet long‑term AI workload demands.
Third, buyers should consider both initial cost and long‑term TCO in their evaluation criteria. This encourages more holistic proposals from vendors and avoids biasing decisions toward lower upfront prices that could result in higher operational costs or performance compromises later.
Finally, procurement teams should work closely with infrastructure architects and AI application owners to ensure that storage choices align with real workload characteristics. Input from these stakeholders can reveal where NVMe provides the most value and help avoid over‑ or under‑provisioning in different parts of the cluster.
Conclusion: NVMe at the heart of AI storage strategies
The jump in enterprise NVMe SSD share in AI data center procurement lists signals a broader transformation in how organizations think about storage. As AI workloads become central to business operations and research, the cost of storage is increasingly measured against its contribution to performance, productivity, and competitiveness. Enterprise NVMe SSDs, with their combination of speed, reliability, and integration into modern architectures, are well suited to meet these demands.
While HDDs and SATA SSDs will continue to play supporting roles, the trajectory is clear: for AI‑driven data centers, enterprise NVMe SSDs are becoming the default choice wherever performance and consistency matter. Buyers, vendors, and operators who recognize and adapt to this shift—through thoughtful procurement, design, and operational practices—will be better positioned to build efficient, scalable AI infrastructures that can keep pace with rapidly evolving workloads and expectations.
You May Like

Narrowing Spread Between NAND Spot and Contract Prices in 2026 – A Signal
By 2026, one of the most watched metrics in the NAND flash market has started to shift in a subtle but meaningful way: the spread between spot prices and long‑term contract prices is narrowing. For casual observers, this may look like just another incremental change in a notoriously volatile industry. For memory makers, module houses, device OEMs, and data center buyers, however, a tightening gap between spot and contract prices is a signal—a reflection of evolving supply–demand balance, risk perceptions, and strategic behavior on both sides of the market.

Price Divergence Trading Strategies Between NAND Flash and DRAM ETFs
NAND flash and DRAM sit at the core of AI storage and computing power. Both are memory, but they are not the same business. DRAM is main memory—fast, volatile, and central to high‑bandwidth workloads like AI training and inference. NAND is non‑volatile storage—slower than DRAM, but crucial to persistent data and large‑scale object storage. The cycles that drive their pricing and margins overlap, yet they often diverge. That divergence is where trading strategies between NAND and DRAM ETFs become interesting.

China’s HBM Localization Progress: The Catch-Up Pace of CXMT and XMC
China’s drive to localize advanced memory technologies has accelerated over the past several years. High-Bandwidth Memory (HBM) sits near the center of that strategy because it is integral to AI accelerators, high-performance computing (HPC) and other strategic compute platforms. Two domestic players—ChangXin Memory Technologies (CXMT) and XMC (Xianghui Memory, commonly referred to as XMC)—have become focal points in assessing how quickly China can close the gap with international incumbents on HBM die, stacking, and packaging.

Thermal Simulation Challenges and Solutions in 3DIC AI Chip Design
As AI workloads push chips to deliver ever higher compute density, designers are increasingly turning to three‑dimensional integration (3DIC) to stack dies vertically and pack more functionality into limited footprints. While 3DIC architectures unlock significant performance and bandwidth advantages, they also introduce complex thermal behaviors that are far harder to predict and manage than in traditional 2D layouts.

An Attempt at Compiling a Memory+Compute Fusion Thematic Index – A Dual-Track Framework
Most AI investors talk about “compute” as if it were the whole story: GPUs, accelerators, chips, cores. But every one of those cores needs somewhere to read from and write to. Memory and storage define how wide the data highway really is. In practice, AI performance is a fusion of compute and memory, not a solo act. So why do so many indices and ETFs separate them into different silos—one for semiconductors, one for memory, one for data centers—when the actual workloads keep blending them?

Surging Demand for Laser Drilling and Plasma Dicing Equipment in Advanced Packaging
Advanced packaging has become one of the semiconductor industry’s most important growth engines, and it is now pulling a surprising set of process tools into the spotlight. Among the most in-demand are laser drilling and plasma dicing equipment. These machines sit close to the heart of heterogeneous integration, fan-out packaging, wafer thinning, TSV formation, glass substrate processing, and other advanced flows where precision, yield, and throughput matter enormously. As packaging moves from a back-end afterthought to a strategic platform, the equipment used to shape, open, and separate materials has become just as important as the dies themselves.

D2D Interface Bandwidth and Latency Comparison in Chiplet Architectures
Chiplet architecture has turned the package into a real performance battleground. Once multiple dies are placed side by side or stacked within the same advanced package, the quality of the die-to-die, or D2D, interface becomes one of the most important determinants of system behavior. Bandwidth is no longer a nice-to-have metric, and latency is no longer a small implementation detail. Together, they shape whether a chiplet system feels nearly monolithic or frustratingly fragmented.

Stock Selection Logic and Alpha Validation of ESG-Themed Semi ETFs
Semiconductor themed ETFs are no longer just about growth and cycles. A growing subset now layers environmental, social, and governance (ESG) criteria on top of traditional sector exposure. These ESG semi ETFs promise two things at once: access to one of the market’s most powerful secular themes, and alignment with sustainability and governance standards. The pitch is appealing, but it raises two hard questions. First, how exactly are these stocks being selected? Second, does the ESG overlay help, hurt, or leave alpha unchanged?