
The Disruptive Impact of CXL Memory Pooling on Enterprise Storage Architecture
Compute Express Link (CXL) is rapidly emerging as one of the most transformative technologies in enterprise infrastructure, and memory pooling is at the heart of its disruptive potential. By decoupling memory from individual servers and exposing it as a shared, dynamically allocable resource, CXL memory pooling challenges long‑standing assumptions about how enterprises design, deploy, and manage both compute and storage.
This blog post examines the disruptive impact of CXL memory pooling on enterprise storage architecture. We begin by explaining what CXL is and how memory pooling works, then explore how it blurs the traditional boundaries between memory and storage, reshapes tiering strategies, affects data services such as caching and snapshots, and alters cost structures and operational models. Finally, we outline practical considerations for architects and IT leaders preparing to integrate CXL memory pooling into their environments.
What CXL is and how memory pooling works
CXL is an industry‑standard, high‑speed interconnect protocol designed to enable low‑latency, high‑bandwidth communication between CPUs and a variety of attached devices, including accelerators, memory expanders, and storage. Built on top of PCI Express, CXL introduces coherency and specialized sub‑protocols that allow devices to share memory in ways that traditional PCIe did not. This opens the door to new architectures where memory is no longer confined to DIMMs on a motherboard but can be extended, pooled, and shared across multiple hosts.
Memory pooling in the CXL context refers to the ability to attach large pools of memory—often via CXL‑attached memory expansion devices—to a fabric and then assign slices of that pooled memory to different servers or workloads dynamically. Rather than provisioning each server with a fixed amount of local DRAM, enterprises can deploy a pool of CXL‑accessible memory that acts as a resource shared across a cluster. Software orchestration layers manage allocation, access, and isolation, making the pooled memory behave like an extension of local memory from the perspective of applications, while still being physically disaggregated.
Traditional enterprise storage vs. CXL‑enabled memory
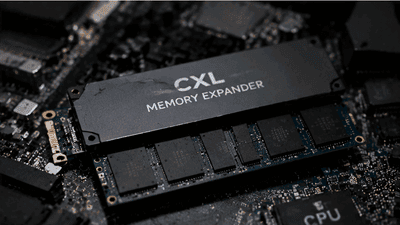
To appreciate the disruptive impact of CXL memory pooling, it helps to contrast it with the traditional enterprise storage model. Historically, storage has been organized into tiers: high‑performance local cache or NVMe, primary block or file storage (often SAN or NAS), and colder archival layers. Memory sits above these tiers as volatile DRAM tightly coupled to individual servers, providing fast access for active data and working sets.
In this model, scaling performance often involved adding more DRAM to each server and deploying faster storage arrays, while scaling capacity meant adding disks or expanding arrays. The separation between memory and storage was clear: memory was fast but limited and per‑server, storage was slower but larger and shared. CXL memory pooling blurs this separation by introducing shared memory resources that have latency and bandwidth characteristics closer to DRAM than to traditional storage, yet are accessible over a fabric like storage.
As a result, enterprise architects must reconsider where the boundary between “memory” and “storage” lies. Pooled CXL memory behaves like an intermediate tier between DRAM and persistent storage, offering capacity that is far larger than per‑server DRAM yet still orders of magnitude faster than conventional storage. This re‑tiering forces a rethink of caching strategies, data placement, and the role of local vs. remote resources.
Blurring the line between memory and storage tiers
One of the most disruptive aspects of CXL memory pooling is how it effectively creates a new tier in the memory–storage hierarchy. Today, enterprises typically think in terms of three main layers: DRAM (fast, volatile, per‑server), high‑performance storage (NVMe, SSDs), and bulk storage (HDDs, object storage, archival media). CXL memory pools sit between DRAM and high‑performance storage, or, depending on implementation, overlapping with aspects of both.
Because CXL memory can be accessed with relatively low latency compared with networked storage, some workloads that previously relied heavily on complex caching schemes or memory‑mapped I/O to local drives can instead leverage pooled memory as a high‑capacity, high‑speed working tier. For example, large in‑memory databases or analytics engines can spill hot data into CXL memory rather than onto disk, reducing I/O complexity and improving performance consistency.
At the same time, this new tier compels architects to revisit storage tier definitions. Instead of thinking of “storage” primarily as persistent media, designers must consider memory‑like tiers that may or may not be persistent but still participate in data management policies. Data lifecycle rules, tier migration strategies, and backup concepts all need adjustment to account for memory pools that behave like storage in some respects but differ in volatility and access semantics.
CXL memory pooling and disaggregated infrastructure
CXL memory pooling aligns naturally with broader trends toward disaggregated and composable infrastructure. In disaggregated architectures, compute, storage, and sometimes memory are separated into pools and then composed dynamically into logical systems. CXL provides the low‑latency fabric and coherency mechanisms needed to make pooled memory feel close enough to local memory for many workloads, while still allowing it to be shared across hosts.
This disaggregation disrupts traditional server‑centric storage architecture. Instead of designing around fixed server configurations with a particular ratio of CPU, DRAM, and storage, enterprises can treat these resources as independent pools. Compute nodes can draw from shared memory pools and shared storage pools as needed, enabling flexible scaling: add more pooled memory when workloads become memory‑intensive, allocate more storage capacity when data volumes grow, and compose these resources into virtual systems on demand.
Such flexibility has significant implications for storage. Storage systems can offload portions of what used to be their job—serving hot data—to pooled memory layers, focusing more on persistence, durability, and capacity. Meanwhile, memory pools take over much of the hot data handling, changing the design of I/O paths, cache layers, and data placement policies throughout the stack.
Implications for caching and tiering strategies
Caching and tiering are central to enterprise storage architecture, and CXL memory pooling alters both. Traditionally, caches have existed in multiple layers: application‑level caches, OS page caches, storage controller caches, and sometimes dedicated caching devices (e.g., NVMe caches in front of HDD arrays). CXL pools introduce a shared, high‑speed resource that can serve as a unified cache or intermediate tier for multiple systems simultaneously.
For example, instead of each server maintaining its own DRAM cache and potentially its own SSD cache, a cluster might use a CXL memory pool as a common caching layer for multiple nodes. Hot data can be stored once in the pool, reducing duplication and improving cache efficiency. This also simplifies the design of distributed storage systems, which can coordinate cache management across nodes more effectively when they share a memory pool.
Tiering strategies likewise change. Data that would traditionally move from DRAM to local SSD and then to remote storage can now flow from DRAM to CXL pools and then to persistent tiers. This intermediate step allows larger working sets to remain in a high‑performance environment longer, delaying or reducing the need to push data down to slower storage. In some cases, CXL memory itself may act as a quasi‑persistent tier if combined with persistent memory technologies or backed by software that provides durability guarantees.
Effects on enterprise storage systems and data services
Enterprise storage systems provide data services such as snapshots, replication, deduplication, compression, and encryption. CXL memory pooling affects how these services are implemented and where they run. When large pools of memory are available over CXL, storage software can leverage them to accelerate metadata operations, index lookups, and data transformations.
For instance, deduplication and compression algorithms can use pooled memory to maintain larger dictionaries or indexes in memory, improving effectiveness and performance. Snapshot management, which often depends on tracking metadata and copy‑on‑write operations, can be optimized by placing key structures in CXL memory, reducing the latency of snapshot creation and access.
However, these benefits come with architectural decisions. Storage systems must determine which data and metadata should live in CXL memory versus traditional storage, considering volatility, cost, and access patterns. They also need to integrate CXL memory into their failure and recovery models, ensuring that reliance on pooled memory does not compromise durability or consistency guarantees.
Cost structures and utilization: shifting the economics
CXL memory pooling disrupts enterprise storage architecture not only technically but economically. Traditional designs often suffer from under‑utilization of memory: each server is provisioned with DRAM for peak load, but average utilization may be much lower, leading to stranded capacity. Storage systems likewise may be over‑provisioned in performance tiers to avoid bottlenecks, adding cost.
By pooling memory, enterprises can improve utilization. Instead of over‑provisioning each server individually, they can deploy a shared pool sized for aggregate needs and dynamically adjust allocations as workloads change. This lowers the overall amount of memory required to meet performance targets, reducing capital expense. It can also allow enterprises to invest in higher‑quality or more advanced memory technologies, since pooled resources amortize cost across many workloads.
On the storage side, pooling and disaggregation can reduce the need for expensive per‑server caching devices, shifting investment toward shared memory tiers and more efficient storage layers. Over time, this may change the balance between spending on high‑performance storage vs. pooled memory, as some performance responsibilities move upward into the memory layer.
At the same time, enterprises must consider new costs associated with CXL: specialized memory expansion devices, CXL‑enabled switches or fabrics, and orchestration software. The economic disruption lies in rebalancing these investments against savings from better utilization and simplified storage performance tuning.
Operational and management changes
CXL memory pooling requires new operational practices and management tools. Traditional storage management focuses on volumes, LUNs, file systems, and object stores; memory management focuses on per‑server capacity and performance monitoring. CXL merges these concerns by making memory a shared, fabric‑connected resource that must be managed with similar discipline to storage pools.
Operators need visibility into pooled memory usage: which workloads are consuming how much, what latency and bandwidth they experience, and how allocations change over time. They must define policies for prioritization and isolation, ensuring that critical applications receive guaranteed memory while multi‑tenant environments avoid contention that could cause unpredictable performance.
Automation becomes more important. Orchestrators must respond to changing workload demands by rebalancing memory allocation across nodes, migrating data between memory and storage tiers, and enforcing policies. This extends existing infrastructure‑as‑code and storage automation paradigms to include memory pools, making resource management more complex but also more powerful.
Security and isolation considerations
Shared memory resources raise security and isolation questions similar to those in shared storage environments. When multiple servers access the same CXL memory pool, strict controls are needed to prevent accidental or malicious data leakage between tenants or workloads. Access control, address space isolation, and monitoring are critical.
Architects must ensure that CXL memory pooling integrates with existing security models, including encryption, authentication, and authorization. For sensitive workloads, they may partition pools or use dedicated memory devices to isolate critical data. Security tools must understand CXL memory as part of the infrastructure, monitoring access patterns and detecting anomalies just as they do for storage.
In regulated environments, compliance frameworks may evolve to address pooled memory explicitly, requiring documentation of isolation mechanisms and audit trails for access. The disruptive impact of CXL thus extends beyond performance and cost into governance and risk management.
Challenges and limitations
While CXL memory pooling offers compelling benefits, it also introduces challenges that temper its disruptive impact. One is complexity: designing and operating a CXL‑enabled memory fabric with proper policies, orchestration, and monitoring requires expertise and mature tooling. Early adopters may face integration hurdles, especially when combining CXL with existing storage infrastructure.
Another challenge is latency sensitivity. Although CXL memory is faster than networked storage, it is typically not identical in latency to local DRAM. Workloads must be evaluated to determine which data structures can live in pooled memory without degrading performance and which still require local DRAM. Misplacing hot data into higher‑latency tiers can negate expected gains.
Additionally, ecosystem maturity matters. The full benefits of CXL memory pooling depend on hardware support from CPUs, memory devices, switches, and accelerators, as well as software support from operating systems, hypervisors, databases, and storage platforms. Until this ecosystem is widely mature and standardized, early designs may be more bespoke and harder to scale.
Practical steps for enterprise architects
Enterprises considering CXL memory pooling should approach it as an evolutionary journey rather than a flip‑of‑a‑switch transformation. A practical starting point is to identify workloads where memory bottlenecks are most severe and where improved utilization would yield clear benefits—such as in‑memory databases, large analytics platforms, or AI training clusters.
Next, architects can evaluate pilot deployments that combine CXL memory expansion devices with existing servers and storage, experimenting with placing caches, metadata, or hot data sets in pooled memory. These pilots help uncover latency behavior, management challenges, and integration issues before broad rollout.
Enterprises should also engage vendors and software providers to understand product roadmaps and integration plans. Storage and database platforms that natively support CXL memory tiers will simplify adoption and maximize benefits. Collaboration between infrastructure teams, application owners, and vendors is crucial to ensure that CXL memory pooling is used where it truly adds value.
Finally, organizations must update governance and documentation to reflect new architectures: defining memory pool usage policies, security constraints, and operational procedures. Treating CXL memory pooling as a first‑class architectural element rather than a niche add‑on helps align teams and investments around its disruptive potential.
Conclusion: CXL memory pooling as a catalyst for storage re‑architecture
CXL memory pooling introduces a shared, high‑performance memory tier that sits between traditional DRAM and storage, reshaping how enterprises design and operate their infrastructure. Its disruptive impact on enterprise storage architecture lies in blurring the boundaries between memory and storage, enabling disaggregated and composable designs, and changing the economics and operational models of performance and capacity management.
While challenges remain in ecosystem maturity, complexity, and security, the trajectory is clear: as CXL spreads and memory pooling becomes more accessible, enterprise storage architectures will evolve to integrate pooled memory as a central component. Organizations that thoughtfully embrace this shift—balancing technical innovation with practical constraints—stand to build more flexible, efficient, and scalable environments for the next generation of data‑intensive workloads.
You May Like

Narrowing Spread Between NAND Spot and Contract Prices in 2026 – A Signal
By 2026, one of the most watched metrics in the NAND flash market has started to shift in a subtle but meaningful way: the spread between spot prices and long‑term contract prices is narrowing. For casual observers, this may look like just another incremental change in a notoriously volatile industry. For memory makers, module houses, device OEMs, and data center buyers, however, a tightening gap between spot and contract prices is a signal—a reflection of evolving supply–demand balance, risk perceptions, and strategic behavior on both sides of the market.

Price Divergence Trading Strategies Between NAND Flash and DRAM ETFs
NAND flash and DRAM sit at the core of AI storage and computing power. Both are memory, but they are not the same business. DRAM is main memory—fast, volatile, and central to high‑bandwidth workloads like AI training and inference. NAND is non‑volatile storage—slower than DRAM, but crucial to persistent data and large‑scale object storage. The cycles that drive their pricing and margins overlap, yet they often diverge. That divergence is where trading strategies between NAND and DRAM ETFs become interesting.

China’s HBM Localization Progress: The Catch-Up Pace of CXMT and XMC
China’s drive to localize advanced memory technologies has accelerated over the past several years. High-Bandwidth Memory (HBM) sits near the center of that strategy because it is integral to AI accelerators, high-performance computing (HPC) and other strategic compute platforms. Two domestic players—ChangXin Memory Technologies (CXMT) and XMC (Xianghui Memory, commonly referred to as XMC)—have become focal points in assessing how quickly China can close the gap with international incumbents on HBM die, stacking, and packaging.

Thermal Simulation Challenges and Solutions in 3DIC AI Chip Design
As AI workloads push chips to deliver ever higher compute density, designers are increasingly turning to three‑dimensional integration (3DIC) to stack dies vertically and pack more functionality into limited footprints. While 3DIC architectures unlock significant performance and bandwidth advantages, they also introduce complex thermal behaviors that are far harder to predict and manage than in traditional 2D layouts.

An Attempt at Compiling a Memory+Compute Fusion Thematic Index – A Dual-Track Framework
Most AI investors talk about “compute” as if it were the whole story: GPUs, accelerators, chips, cores. But every one of those cores needs somewhere to read from and write to. Memory and storage define how wide the data highway really is. In practice, AI performance is a fusion of compute and memory, not a solo act. So why do so many indices and ETFs separate them into different silos—one for semiconductors, one for memory, one for data centers—when the actual workloads keep blending them?

Surging Demand for Laser Drilling and Plasma Dicing Equipment in Advanced Packaging
Advanced packaging has become one of the semiconductor industry’s most important growth engines, and it is now pulling a surprising set of process tools into the spotlight. Among the most in-demand are laser drilling and plasma dicing equipment. These machines sit close to the heart of heterogeneous integration, fan-out packaging, wafer thinning, TSV formation, glass substrate processing, and other advanced flows where precision, yield, and throughput matter enormously. As packaging moves from a back-end afterthought to a strategic platform, the equipment used to shape, open, and separate materials has become just as important as the dies themselves.

D2D Interface Bandwidth and Latency Comparison in Chiplet Architectures
Chiplet architecture has turned the package into a real performance battleground. Once multiple dies are placed side by side or stacked within the same advanced package, the quality of the die-to-die, or D2D, interface becomes one of the most important determinants of system behavior. Bandwidth is no longer a nice-to-have metric, and latency is no longer a small implementation detail. Together, they shape whether a chiplet system feels nearly monolithic or frustratingly fragmented.

Stock Selection Logic and Alpha Validation of ESG-Themed Semi ETFs
Semiconductor themed ETFs are no longer just about growth and cycles. A growing subset now layers environmental, social, and governance (ESG) criteria on top of traditional sector exposure. These ESG semi ETFs promise two things at once: access to one of the market’s most powerful secular themes, and alignment with sustainability and governance standards. The pitch is appealing, but it raises two hard questions. First, how exactly are these stocks being selected? Second, does the ESG overlay help, hurt, or leave alpha unchanged?